Comments in CSV files are those lines or parts of lines preceded by a specific character. For example, the following CSV data have comments introduced by the “#” symbol (the data is saved as employees-roles.csv).
# This data should be joined with employee names
# extraction started
employee_id,Role,Department
1,CEO,Management
2,CFO,Management
3,Managing director,Management# Officer
# Data point couldn't be fetched
5,Data analyst,Data
6,Software developer,Technology
# extraction completed
# this is the end
This article discusses two methods for removing commented content, like lines 1, 2, 6 (partly commented), 7, 10, and 11, in the CSV data above.
Method 1: Using the Pandas Package
The pandas.read_csv() function has a “comments” attribute that can be used to specify and remove comments in the loaded CSV file.
You may need to install or upgrade pandas using pip with the following command:
pip install -U pandasNote: the code below was tested on pandas v2.0.2.
The following code can be used to remove comments on the CSV file given above.
import pandas as pd

df = pd.read_csv("employees-roles.csv",
             	sep=",", 	# the delimiter
             	comment="#", # comment character
             	skipinitialspace=True, # Skip white spaces after delimiter
             	skip_blank_lines=True, # Ignore blank lines when parsing
             	on_bad_lines="warn" # available on pandas 1.3.0 and later
             	).reset_index(drop=True)
# Commented lines would be counted on the index; therefore, we need to reset the index and drop
# the old index so that it doesn't create a new column
print(df)
Output:
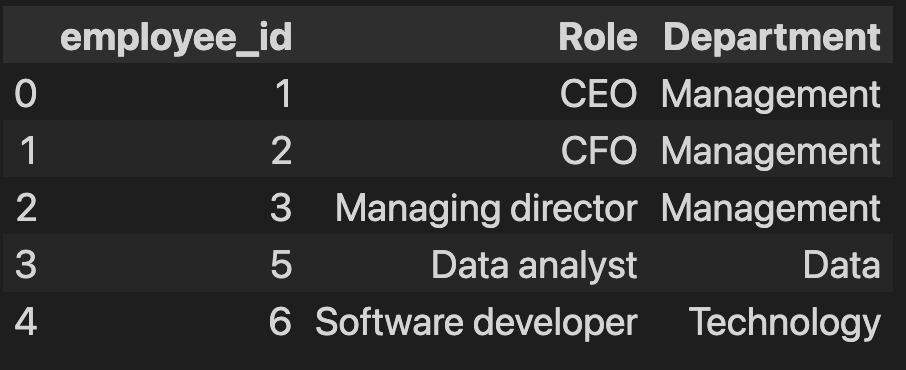
The output above shows that all comments were ignored – including the partly commented part at index=2 of the output. If you want to only ignore lines that are wholly commented, then Method 2 should serve the purpose.
Method 2: Using csv package
If you are using csv package to manipulate your CSV data, then this method is for you.
Let’s start with the case when we want to only ignore lines that were fully commented out.
import csv

with open("employees-roles.csv") as infile:
    # Lambda function ignores all lines starting with "#".
    reader = csv.reader(filter(lambda row: row[0] != "#", infile))
    # Then loop through the uncommented lines
    for row in reader:
        print(row)
Output:
['employee_id', 'Role', 'Department']
['1', 'CEO', 'Management']
['2', 'CFO', 'Management']
['3', 'Managing director', 'Management# Officer']
['5', 'Data analyst', 'Data']
['6', 'Software developer', 'Technology']
As shown in the output, the code above only removed lines that were commented out – it did not remove partly commented lines like in line 4 of the output.
If you want to remove all commented content, the following code should suffice.
import csv

with open("employees-roles.csv", "r") as infile:
    reader = csv.reader(infile, delimiter=",")
    for row in reader:
        # This line comprehension loops through each cell of the row and remove commented parts
        modified_row = [
            cell if not "#" in cell else cell.split("#")[0].strip() for cell in row
        ]
        # modifiled_row = [""] for commented lines; therefore, we need an if-statement to ignore such
        if len(modified_row) == 1 and modified_row[0] == "":
            continue
        print(modified_row)
Output:
['employee_id', 'Role', 'Department']
['1', 'CEO', 'Management']
['2', 'CFO', 'Management']
['3', 'Managing director', 'Management']
['5', 'Data analyst', 'Data']
['6', 'Software developer', 'Technology']
You can also rewrite the code above, as shown below. This approach is particularly useful when you intend to read many CSV files and use one function to remove comments for each.
import csv

def remove_comments(csvfile):
    # Loop through the CSV file, remove comments, and yield the result
    for row in csvfile:
        raw = row.split("#")[0].strip()
        if len(raw) != 0:
            yield raw
with open("employees-roles.csv", "r") as csvfile:
    # Apply the remove_comments function
    reader = csv.reader(remove_comments(csvfile))
    for row in reader:
        print(row)
Output:
['employee_id', 'Role', 'Department']
['1', 'CEO', 'Management']
['2', 'CFO', 'Management']
['3', 'Managing director', 'Management']
['5', 'Data analyst', 'Data']
['6', 'Software developer', 'Technology']
Conclusion
This article discussed using pandas and csv packages to ignore comments when loading CSV files in Python. Method 1 (using pandas) ignores comments anywhere in the file. In Method 2, we covered how to use csv package in two cases – to ignore lines that are wholly commented out and/or parts of lines that are partly commented out.